Balancing Scalability and Principles in Large-Scale System Automation
High-Volume Traffic Circulation for modern automation
Automation reached a brand-new peak in 2026 as organizations scaled up their information extraction and network tasks. Dealing with ten million demands per minute needs more than simply a single server or an easy proxy list. It requires a sophisticated method to traffic circulation. When managing massive botnets or dispersed scrapers, the primary objective is to guarantee that no single node ends up being a bottleneck or a target for detection. This is where load balancing steps in, acting as the traffic controller for millions of synchronised connections across a worldwide network.The shift toward dispersed architectures in 2026 has actually altered how engineers see automation. Instead of a centralized command-and-center model, modern systems utilize decentralized nodes that communicate through a smart middle layer. This layer chooses which proxy to utilize, which area to path through, and how to deal with a sudden surge in target site defenses. Without this control, a massive scraping operation would collapse under its own weight, either through self-inflicted denial-of-service or by setting off aggressive anti-bot filters.Managing the circulation of requests starts with understanding the distinction in between Layer 4 and Layer 7 balancing. In the context of scraping, Layer 7 (application layer) balancing is typically more useful since it enables the system to make choices based upon the material of the demand. For instance, if a scraper is targeting a specific product page, the balancer can path that demand to a proxy that has actually recently effectively accessed that exact domain. Organizations typically look towards Wikipedia Info to manage these inbound information streams. This level of granularity ensures that the network stays efficient and minimizes the variety of failed demands.
Technical Requirements for high-scale operations
Scalability in 2026 depends on the ability to include or get rid of capability on the fly. When a scraper starts an enormous crawl of a retail website throughout a vacation sale, the facilities needs to broaden instantly. Standard load balancers sometimes deal with the quick connection churn associated with botnets. Each bot may only stay active for a couple of seconds before turning its IP or closing down to prevent detection. This continuous starting and stopping of connections puts enormous pressure on the balancing software.To counter this, many developers have actually turned to "Anycast" networking. This permits numerous servers to share the very same IP address, with the network routing traffic to the closest offered node. In a scraping context, this assists reduce latency and makes the botnet appear more like legitimate, distributed user traffic. When a bot in Tokyo makes a demand, it strikes a regional entry point instead of taking a trip throughout the ocean to a central server. This local routing is a key part of remaining under the radar of modern-day security systems that search for uncommon geographic traffic patterns.The hardware side of the formula has also progressed. Specialized network cards and high-speed memory are now standard for handling the state tables of millions of concurrent sessions. If a balancer misplaces which bot is doing what, the whole scraping run can lose its location, leading to replicate data or missed pages. Stability is the most important metric here. Using durable, proven hardware configurations allows these networks to keep 99.9% uptime even during peak loads.
Dealing With Site Defenses via advanced rotation
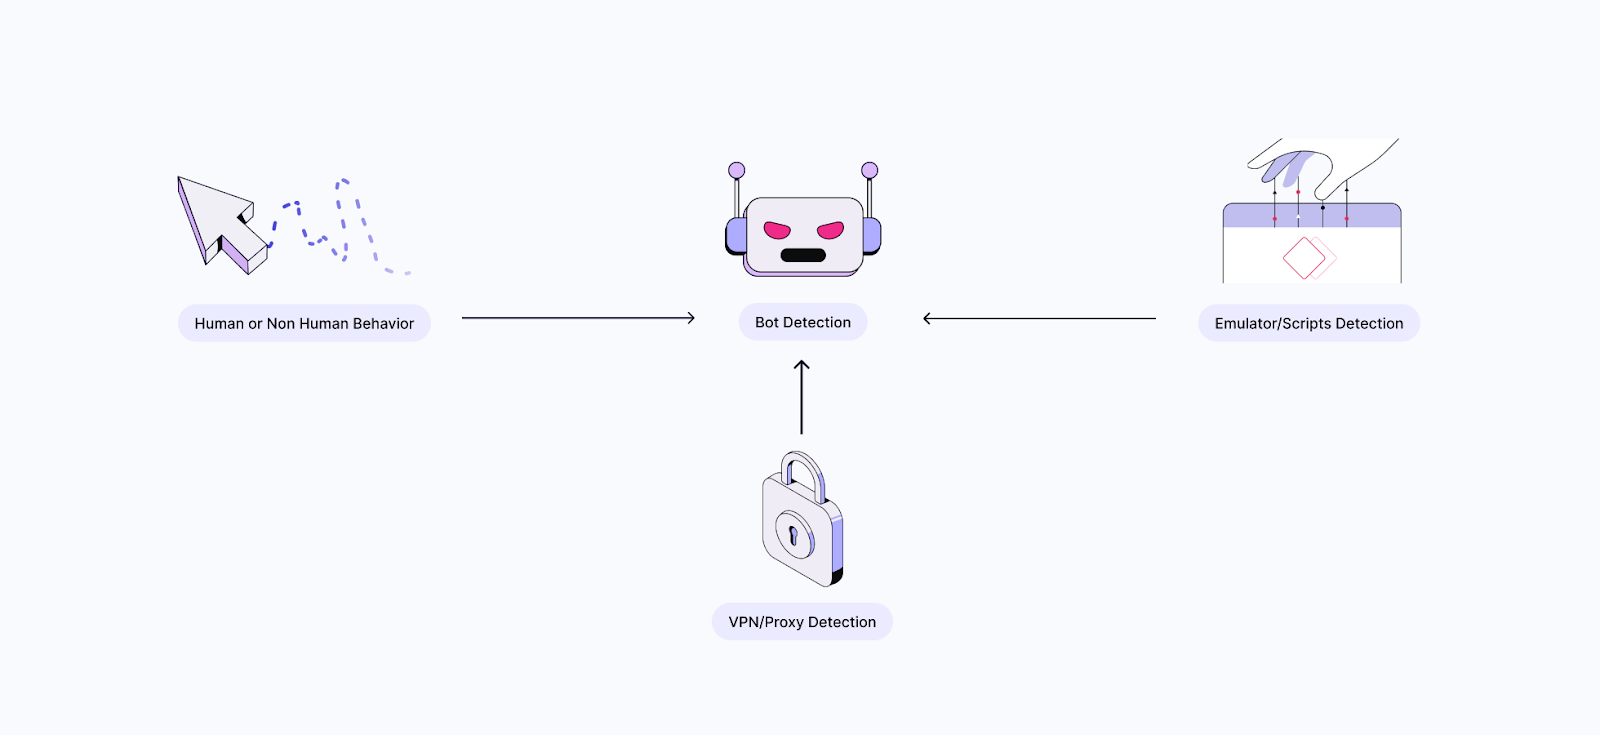
Anti-bot innovation in 2026 is much faster and more accurate than ever before. Websites now utilize behavioral analysis to spot patterns that look "too ideal" or "too quickly." Load balancing helps break these patterns by presenting jitter and varied timing into the request flow. An excellent balancer doesn't just distribute traffic uniformly; it distributes it arbitrarily within particular specifications to imitate human behavior.One of the most significant obstacles is the sudden look of a difficulty or a block. When a target website detects suspicious activity, it may issue a momentary IP restriction or reveal a captcha. A wise load balancer detects these 403 or 429 status codes right away. It can then immediately pull that particular proxy out of the rotation and change it with a fresh one. Efficient implementation of Wikipedia XRumer Wiki Data simplifies the procedure of turning sensitive qualifications. This proactive management avoids the botnet from burning through its entire IP swimming pool in a matter of minutes.Predictive scaling is another function becoming typical in 2026. By examining historic information, a balancer can predict when a target site is likely to increase its security or when a specific proxy provider is most likely to experience downtime. The system can then move traffic to more trusted paths before the failures really occur. This keeps the information flowing and reduces the requirement for manual intervention by the engineering team.
Proxy Management and IP Diversity
The heart of any enormous scraper is its proxy swimming pool. In 2026, the diversity of these proxies is what figures out the success of a task. Using only data center IPs is no longer enough for most high-value targets. Instead, networks utilize a mix of property, mobile, and information center addresses. The load balancer should be mindful of the "reputation" of each IP type. Residential IPs are more expensive and slower, so the balancer should use them sparingly-- just for the most challenging pages.Data center IPs are utilized for the "heavy lifting"-- the preliminary discovery of URLs or scraping sites with lower security. The balancer functions as a reasoning gate, choosing which "tier" of proxy to use based on the intricacy of the task. This tiered approach conserves money and protects the "health" of the residential IP pool. If a balancer sends too many requests through a property node, it might get flagged by the ISP, triggering the home user to discover a downturn and potentially resulting in the IP being pulled from the service.Mobile proxies are the most elusive in 2026. They share IPs with countless real users, making them nearly impossible to obstruct without also obstructing legitimate customers. They are also the most restricted in terms of bandwidth. A load balancer needs to strictly keep track of the data use on mobile nodes to avoid hitting caps or triggering informs on the mobile carrier's network. This cautious orchestration of various IP types is what enables a botnet to remain functional over long durations.
The Future of Distributed Computing
As we look further into 2026, the line between a botnet and a legitimate dispersed system is blurring. The same innovation utilized to scrape public information is also used for tension screening, worldwide material delivery, and marketing research. The focus has moved from "the number of bots can I run?" to "how wisely can I manage the ones I have?" High-efficiency balancing is the answer to that question.The approach "serverless" scraping is the next big step. In this design, the load balancer doesn't simply send traffic to a standing server. It triggers a brief function that performs the scrape and then disappears. This makes the infrastructure a lot more difficult to track and block. The balancer ends up being the orchestrator of countless tiny, ephemeral occasions. It handles the lifecycle of each request from birth to conclusion, ensuring that the data is caught and kept correctly.Security for the botnet itself is also a concern. In 2026, competitive scraping is typical, where one group may attempt to hijack or interfere with another group's network. Load balancers now include their own internal firewalls and file encryption to make sure that the command-and-control signals aren't intercepted. This produces a safe tunnel between the supervisor and the employee nodes, protecting the integrity of the operation.
Last Considerations for Network Architects
Constructing a system of this scale in 2026 needs a deep understanding of both networking and software application development. It isn't adequate to simply purchase a load balancer and turn it on. The configuration needs to be tuned to the specific requirements of the scraping job. Every millisecond of latency and every stopped working demand has an expense. By focusing on intelligent traffic distribution and proactive IP management, engineers can build automation systems that are both effective and resilient.The use of https://en.wikipedia.org/wiki/XRumer helps bridge the space between raw data and usable insights. Whether the goal is rate monitoring, social media analysis, or scholastic research study, the infrastructure is what makes it possible. As the volume of information on the internet continues to grow, the tools we use to gather it needs to grow also. Load balancing is no longer a high-end for massive botnets; it is the essential requirement for any serious automation task in 2026. Those who master these circulation techniques discover themselves with a substantial advantage. They can collect more information, quicker, and with fewer blocks than their competitors. In a world where information is the most important resource, the ability to collect it at scale is the supreme power. The intricacy of these systems will only increase, however the core concepts of balance, rotation, and intelligence will remain the exact same. Over the next year, anticipate to see even more automation in the balancing process itself, as AI begins to take over the role of the traffic controller.